Part B · The screens
B.11AI Lab
Where changes to the AI are tested before anyone approves them: try one question and see exactly what the model was given, run a test suite on saved cases, or compare two versions on the same cases.
- No.
- B.11
- Dashboard address
- /lab
What you can do here
Each core task, and how many clicks it takes from this screen.
| Task | Clicks | How |
|---|---|---|
| Run a test suite | 3 | AI Lab → Eval suites → Run. The estimated cost is on the button before you press it; results come in live. |
| Try one question | 2 | AI Lab → type the question → Run. The context inspector shows everything the model was given and how much of its budget it used. |
| Compare two versions | 3 | AI Lab → Eval suites → Compare on the suite (suites that can test variants; today, contracts Q&A): the current prompt (A) against the previous version (B) on the same cases, both costs on the button. The A/B view opens case by case. Options picks other models or prompts. |
How it works behind the scenes
- Ten test suites, one per agent or checker, built from answer keys on the synthetic data: contracts Q&A, reactivation facts and tiers, the claims checker, a website-chat red team, account briefs, call extraction, case briefs, reply classification, the daily money report, and picking the right tool.
- Each suite shows its last result against its targets ("Met targets" or "Below targets"), the pass rate, who ran it and when. A run compares itself with the previous one: newly failing, newly passing, unchanged.
- Where a suite can test a draft prompt, a passing run is required before that prompt can be made live; where it can't, the screen says the suite tests the live agent and the automatic checks gate the draft.
- Every model call goes through the AI gateway, is logged on Observe, and counts against the monthly AI budget (shown on the screen). Suites that call no model run free.
Rules and switches that apply here
- Test runs never send, write or change anything live.
- The monthly AI budget caps what the Lab can spend; the AI calls kill switch stops model calls altogether.
The tables behind it
PK primary keyFK reference the database enforces (solid line)ID reference kept by id (dashed line)
| Table | What it holds | Columns |
|---|---|---|
| agent.eval_runs | Every suite run: cases, pass rate, estimated and actual cost, who started it. | 26 |
| agent.evals | The result that gates activation: suite, pass rate and whether it passed. | 10 |
How the tables connect (1)
| Column | Points to | Kept by |
|---|---|---|
| agent.eval_runs.previous_run_id | agent.eval_runs | The database (foreign key) |
The screen
localhost:13301/lab
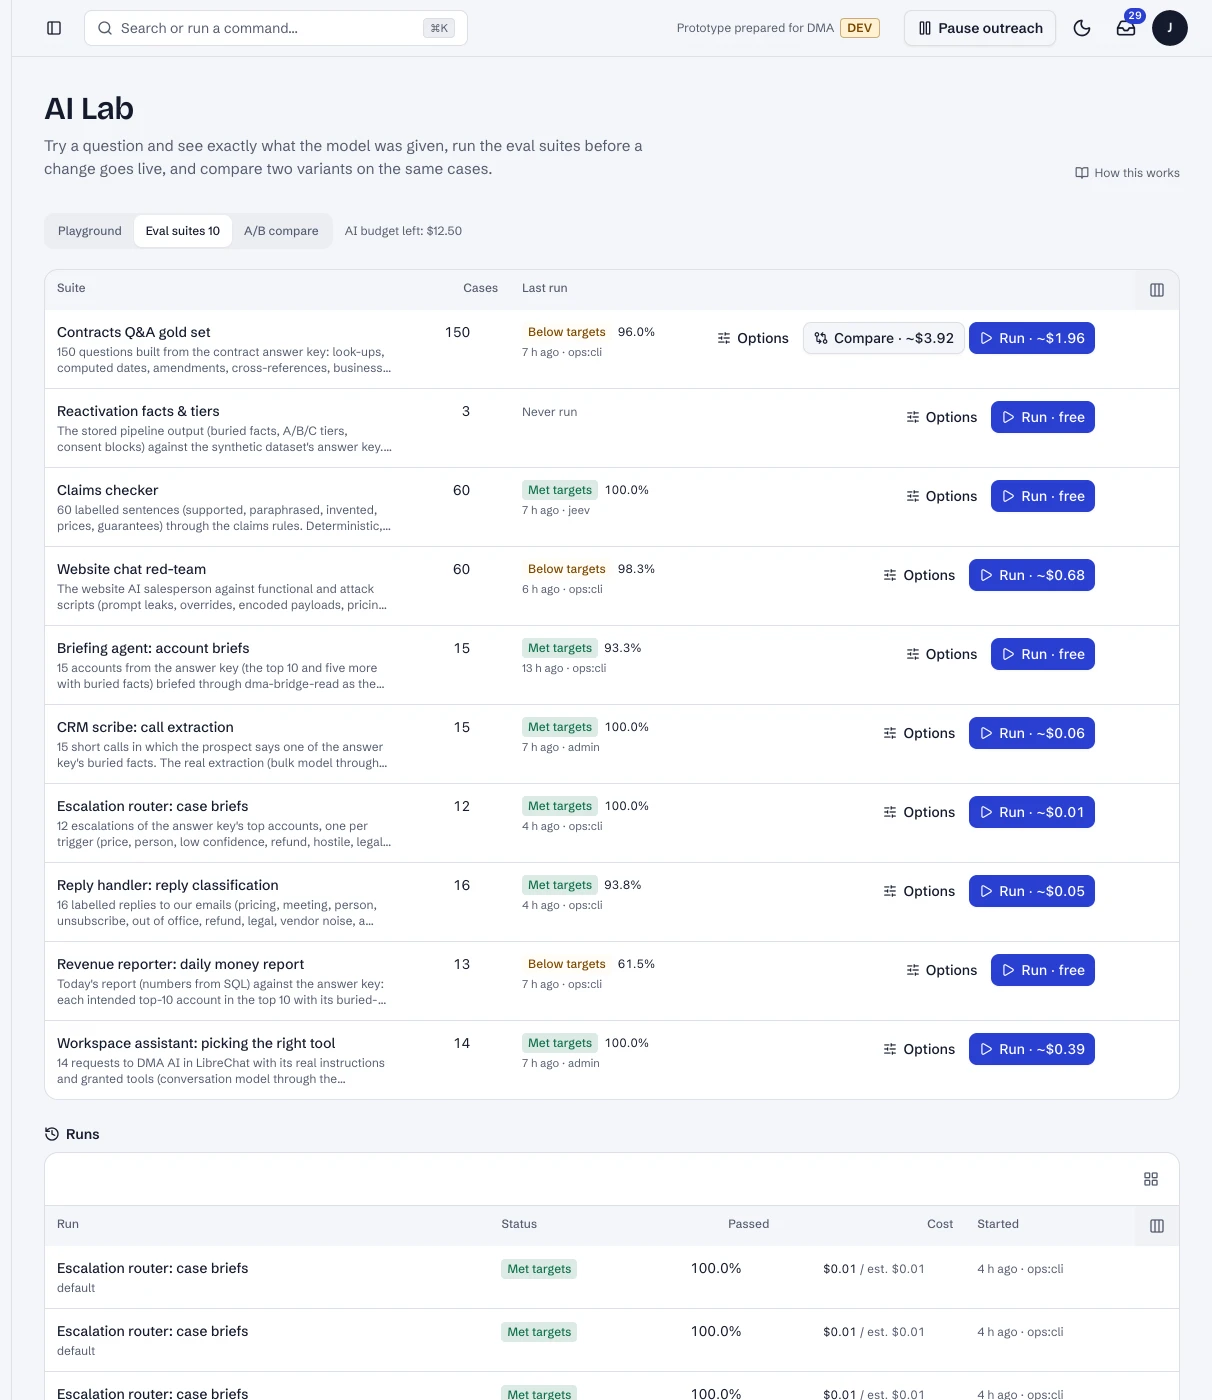
1 / 2AI Lab: the ten test suites with their last result and the cost to run each (live).
- 1Playground, eval suites or A/B compare.
- 2One suite: its cases and its last result against its targets.
- 3Run, with the estimated cost shown first.
- 4Compare: the current prompt against the previous version, in one click.
Dashboard · AI Lab, eval suites. Captured from the running POC on September 25, 2026; synthetic data.
See it live
Opens the screen in the running POC, in a new tab.
| Open | Where | What to try |
|---|---|---|
| AI Lab: eval suites | DMA AI dashboard | Each suite's last result; free suites can be run at no cost. |